 Busirank Team
Introduction
Brand voice has always been hard to scale. A tone-of-voice document gets written once, circulated to regional managers, and then erodes slowly as forty different people write reviews and posts in forty different styles. AI was supposed to fix this. In practice, poorly configured AI makes it worse: an LLM with no voice reference falls back to the median of its training data, which is why so many AI-generated replies sound like the same cheerful, hollow customer-service script.
The goal is not “AI that writes well.” It is AI that writes like you, at every location, every time. That requires a different setup than most teams build. You need a voice reference the model can actually follow, guardrails that enforce the non-negotiables, a structure that lets local detail vary without letting the brand fracture, and a monitoring habit that catches drift before customers do.
The stakes are concrete. Alchemer’s March 2026 Brand Tracker found that 37% of teams want AI to automate repetitive tasks, yet fewer than 30% are comfortable letting AI act without human review. The gap between those two numbers is exactly the problem this guide solves: how to let AI speak for you without losing control of how you sound.
Why AI Brand Voice Drifts Across Locations
Brand voice drift is not a technology failure. It is a governance failure. Google Reviews at Scale describes the mechanism precisely: voice drifts between locations when 40 different store managers are each writing replies in their own style, with no one checking tone across the network. AI does not create the problem—it accelerates it, because the model will imitate whatever examples or instructions it is given, and different locations will give it different inputs.
There is a second, subtler form of drift that only appears after setup. Brand voice can drift subtly over time as AI systems update, which is why governance requires ongoing auditing rather than a one-time setup check. A workflow that sounded right in January can sound slightly off by July, not because anyone changed the prompt, but because the model or the business changed around it. Drift detection needs to be a standing process, with 90-day review cycles identified as the right resolution—monthly checks generate noise, and annual checks miss the drift entirely.
The third form is the one most teams miss: identical voice is also a drift problem. When every location posts the same reply under the same brand name, customers read it as “nobody here is listening.” Consistency is not sameness. The target is a recognizable voice with local specificity—the brand writes the sentence, the location supplies the detail.
Step 1: Build a Machine-Readable Voice Reference
The most common mistake is giving the AI adjectives (“friendly,” “professional,” “warm”) instead of examples and rules. Models are much better at imitation than at inference from vague descriptions. The consistent finding across tools and practitioners is that 3–5 real example replies are enough to establish a usable baseline, and that the model extracts vocabulary patterns, sentence length, and phrasing preferences from those samples.
CoSchedule’s Brand Profiles show what a complete voice reference looks like structurally. It includes a Company Profile for key business information, a Style Guide for grammar and writing rules, Brand Voice rules that avoid certain words and repetitive sentence structures, Products & Services for precision, Customer Reviews as authentic social proof, and Business Locations so the AI can reference the right place in content. The inclusion of Business Locations is the multi-location detail that matters: a single brand profile with location data produces replies that can reference the branch, not just the brand.
For a marketing team building this from scratch, the voice reference should contain four things:
- Three to five real replies you would be proud to publish, across positive, neutral, and mildly negative reviews.
- A short style guide covering sentence length, formality, and whether you use contractions, emoji, or the customer’s first name.
- A business facts file with products, services, common complaints, and the location list.
- A banned list—the words, phrases, and structures that must never appear.
Refresh the examples when the business changes tone, services, or locations. A voice reference is a living document, not a one-time upload.
Step 2: Write Guardrails That Are Specific Enough to Enforce
Guardrails are where brand voice becomes operational. The governing principle, stated plainly by Promorepublic’s AI governance guide, is to document your brand voice in AI-usable format: specific examples of on-brand and off-brand language, prohibited phrases, and content category rules.
Vague guardrails fail. Manychat’s documentation makes the point with a concrete contrast: instead of “don’t give advice,” write “never provide specific legal or financial advice regarding business structures or taxes”. The same discipline applies to voice. “Be friendly” is not a guardrail. These are:
- Openings: “Never open with ‘Thank you for your kind words.’ Open with the customer’s name or a detail from the review.”
- Length: “Two to four sentences. No exceptions.”
- Specificity: “Reference one concrete detail from the review text.”
- Vocabulary: “Never use ‘thrilled,’ ‘valued feedback,’ or ‘your satisfaction is our priority.’”
- Promises: “Never promise refunds, remedies, or timelines without approval”.
- Facts: “Never invent details about the job, visit, patient, client, or order”.
The compliance layer matters as much as the tone layer. CoSchedule separates Compliance Check (legal and regulatory rules) from Brand Voice rules (style and word avoidance), so a reply cannot pass the voice test while failing the compliance test. For regulated industries—healthcare, financial services, insurance—this separation is not optional.
Step 3: Let Local Detail Vary Without Letting the Brand Fracture
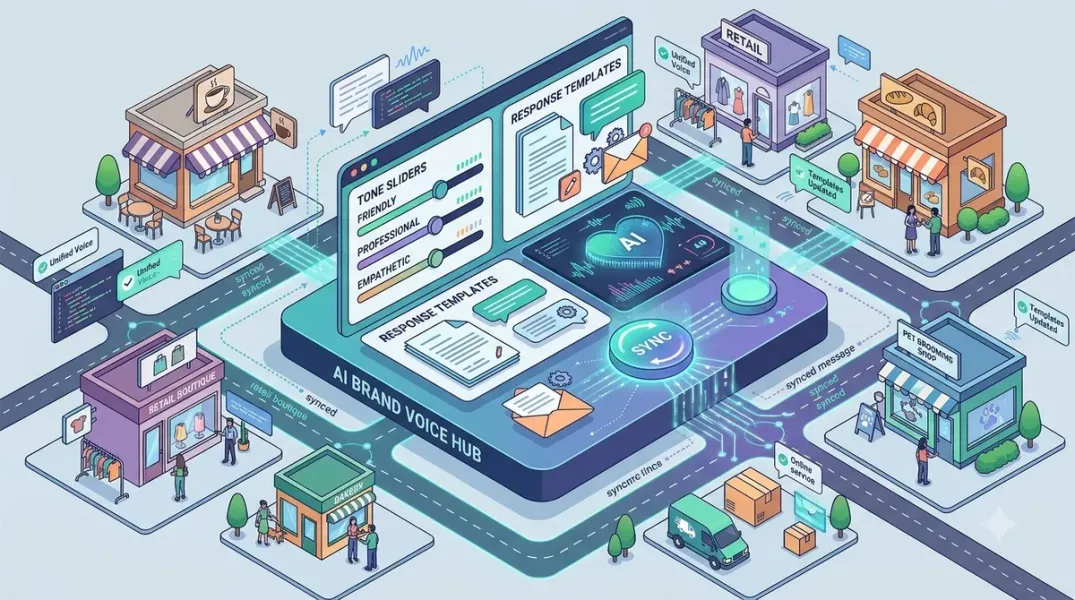
The multi-location voice problem is solved by separating what must be central from what should be local. Birdeye’s franchise model describes the right architecture: Corporate sets the strategy and guardrails; local teams add authentic local content—no bottlenecks, no compliance risk.
The tooling now supports this at the settings level. Local Falcon lets you enable automatic review responses for a single location or many at once, with custom per-location response rules so each reply feels relevant, personalized, and on-brand. GMBMantra goes further: brand voice is per-location, so a salon and a clinic on the same account each get their own voice without one overwriting the other, and each location has its own automation cadence. StarReplies exposes the same control in a location configuration panel where you set tone, length, and style per location.
The operating rule is: the voice is central, the details are local. Central guardrails define how the brand speaks. Per-location settings allow the greeting style, sign-off, and local vocabulary to differ where it should. And a location context rule keeps every reply aligned to the correct Business Profile and service context—so a reply about a plumbing job never lands under the landscaping location.
This is the difference between consistency and homogeneity. Customers should be able to tell that two branches belong to the same brand without being able to tell that the same machine wrote both replies.
Step 4: Tier the Automation by Risk
Voice consistency does not require human review of every reply. It requires human review of the right replies. The tiering model that appears consistently across the 2026 tooling landscape is the one to adopt.
Birdeye’s Review Response Agent, deployed across 400 Stellar Service Brands locations, runs a clean split: four- and five-star reviews are automatically replied to and posted with no manual intervention; three-star and below are flagged, a suggested reply is generated, and the franchise owner steps in; sensitive feedback gets human attention. The agent is trained on Stellar’s brand voice across each of its brands, so every reply feels like it came from someone who knows the customer. The result was a response rate rise from 60% to 87%, with no added workload for franchise owners or corporate staff.
The same pattern appears at Rita’s Italian Ice: before automation, the team spent 8–10 hours a week keeping up with reviews; after deploying AI-powered reputation agents, review and guidance takes about 5 minutes a day, with faster replies at every location and “one brand voice without burning out the humans”.
The risk tier is the automation boundary. Routine positive reviews can move at machine speed because the voice reference and guardrails are doing the work. Low-star and sensitive reviews stay in human approval because the judgment call is not about tone—it is about facts, accountability, and legal exposure.
Step 5: Monitor for Drift, Not Just Errors
Voice drift is invisible in a per-review quality check. Every individual reply can look acceptable while the aggregate quietly moves away from the brand. The monitoring job is therefore a sampling job, not an approval job.
The recommended cadence is a monthly audit where someone at head office reads a sample of auto-posted replies across the network to check for tone drift. Score each sampled reply against the voice reference—does it match the examples, does it avoid the banned phrases, does it reference a real detail—and route borderline cases to a batched review queue rather than publishing them.
The audit should ask three questions: Is the voice still ours? Is the voice the same across locations? Is the local detail still present, or has it collapsed into generic brand boilerplate? If the answer to the third question is “generic,” the per-location settings have been overridden or abandoned, and the fix is upstream in the configuration, not in the individual replies.
Run the audit on a schedule, not when something goes wrong. The 90-day cycle is the right resolution for strategic drift; monthly sampling catches operational drift before it compounds.
Conclusion
A consistent AI brand voice across every location is not achieved by writing a better prompt. It is achieved by building a system with four layers: a machine-readable voice reference built from real examples, guardrails specific enough to enforce the non-negotiables, per-location settings that let local detail vary, and a monitoring habit that catches drift on a schedule.
The operators who have done this are not choosing between scale and authenticity. Stellar Service Brands went from 60% to 87% response coverage across 400 locations with replies trained on its brand voice. Rita’s Italian Ice cut review management from 8–10 hours a week to 5 minutes a day without losing “one brand voice.” The pattern is consistent: central voice, local detail, risk-tiered approval, scheduled audit. Get those four right, and AI becomes a brand conductor rather than a source of generic noise.
Get them wrong, and the result is the opposite: forty locations sounding like forty different companies, or worse, forty locations sounding like the same machine.
Call to Action
Start with three replies, not thirty settings. Pick three real review responses you would be proud to publish at any location—one positive, one neutral, one mildly negative. Paste them into your AI tool’s voice samples field. Then write five guardrails: one banned opening, one banned phrase, one length limit, one specificity rule, and one no-promises rule. Run the workflow in draft-only mode for two weeks and read every reply. If the drafts sound like your three examples and obey all five guardrails, you have a working voice reference. Then enable per-location settings for the local detail, and put a monthly 15-minute sample audit on the calendar before you turn on any auto-publish tier.
FAQs
How many example replies do I need to train an AI on my brand voice?Three to five real replies is the consistent baseline across tools and practitioner guides. ReviewPilot extracts vocabulary patterns, sentence length, and phrasing preferences from 3–5 samples. Local Review Reply’s safe workflow starts with 3–5 real example replies and refreshes them when the business changes tone, services, or locations.
What is brand voice drift and why does it happen?Drift is the gradual erosion of a consistent voice across locations or over time. It happens when different managers write in their own styles with no cross-network tone check, and it can also happen when AI systems update and the model’s output shifts slightly. It requires scheduled auditing—90-day cycles are recommended—rather than a one-time setup check.
Can each location have its own voice without breaking brand consistency?Yes, and in many tools it should. Per-location brand voice settings let a salon and a clinic on the same account each have their own voice, and per-location response rules let replies feel local while still following central guardrails. The rule is central voice, local detail—not identical replies under every branch.
Should AI auto-post replies to all reviews?No. The proven split is to auto-post four- and five-star reviews, flag three-star and below for a human, and route sensitive feedback to a person immediately. Stellar Service Brands runs this model across 400 locations and lifted its response rate from 60% to 87% without adding workload.
What should be in a brand voice guardrail?Specific, enforceable rules: banned opening phrases, banned vocabulary, a sentence-length limit, a requirement to reference a concrete review detail, a no-promises rule, and a no-invented-facts rule. Vague instructions like “be friendly” do not function as guardrails. Compliance rules (legal, regulatory) should sit separately from style rules.
How do I know if my AI voice has drifted?Sample auto-posted replies across locations every month and score them against your voice reference. Ask three questions: does it match the examples, does it avoid the banned phrases, and does it still contain local detail? If the detail has collapsed into generic brand boilerplate, the per-location configuration has been overridden or abandoned.
Which tools support per-location AI brand voice?Birdeye’s Brand AI trains agents on your voice and supports per-location permissions and tiered approvals. Local Falcon supports custom per-location response rules. GMBMantra applies brand voice per location so different business types on one account do not overwrite each other. CoSchedule’s Brand Profiles include Business Locations in the voice reference. Local Review Reply’s workflow uses location-specific examples so replies sound local while following central approval rules.
Internal & External Links
Internal links (to other posts in this series):
- How to Manage Google Reviews From Multiple Locations in One Dashboard (previous post)
- How to Automate Google Review Responses Without Losing Your Brand Voice
- How to Set Up Review Approval Workflows for Your Marketing Team
- How to Audit Your Team’s Review Responses for Quality and Consistency
- How to Plan Google Business Profile Content Around Seasonal Promotions
- How to Standardize Local Marketing Tasks Across a Distributed Team
External links (sources referenced in this article):
- CoSchedule — Brand Profiles Turn AI Into Your Brand’s Best Writer: https://coschedule.com/announcements/coschedule-brand-profiles
- Local Falcon — How To Enable Automatic Review Responses: https://www.localfalcon.com/knowledge-base/kb97-how-to-enable-automatic-review-responses
- Local Review Reply — AI Google Review Response Workflow: https://localreviewreply.com/guides/ai-google-review-response
- Birdeye — Franchise Marketing Software: https://birdeye.com/franchise/
- Birdeye — Stellar Service Brands Case Study: https://birdeye.com/sg/resources/case-studies/stellar-service-brands/
- Promorepublic — How to Govern AI Local Marketing Across Locations: https://promorepublic.com
- Automata AI — Google Reviews at Scale: Response Workflows for Multi-Site Operators: https://www.automataai.com.au
- Manychat Help — AI Behavior Guardrails: https://help.manychat.com
- ReviewPilot — Choose Your Reply Tone: https://reviewpilot.co.in
- GMBMantra — AI-Powered Google Business Profile Management: https://gmbmantra.ai
- StarReplies — Managing Location Settings: https://starreplies.com
- Alchemer Brand Tracker (March 2026), cited via Birdeye: https://birdeye.com
- Rita’s Italian Ice / SOCi.ai (LinkedIn): https://www.linkedin.com/posts/activity-7417196294051356672-fFIM
How to Schedule a Month of Google Business Posts in One Sitting
Grow Your Google Maps Ranking on Autopilot
Stop spending hours every week manually replying to customer reviews and writing Google posts. Busirank automates your Google Business Profile to boost your local SEO rankings and turn searchers into paying clients.
 Busirank Team