 Busirank Team
Introduction
A location database that works for ten stores will break at a hundred. The spreadsheet that served a regional chain will collapse when you expand nationally. This is not a matter of effort—it is a matter of architecture.
When Zepto scaled its real-time delivery platform, the geospatial backbone that worked flawlessly in early stages developed a peculiar problem: 20% of servers did the work of 80%. The system was not broken. It was built for a scale it had outgrown. The same pattern repeats in location databases across every industry. The structure that got you here will not get you there.
Building a location database that scales requires deliberate choices about data modeling, geospatial indexing, and how location data flows into every system that depends on it. This guide explains those choices, drawing on how companies like Domino’s Pizza, SafeGraph, and Zepto solved the same challenges at scale.
The foundation of a scalable location database is its data model. A schema that works for a handful of locations often fails at scale because it lacks the fields needed for geospatial queries, territory management, or hierarchical organization.
A practical starting point comes from a fitness franchise system that needed to manage multiple gym locations, each operating independently with its own schedules, coaches, and business rules. Their locations table includes the fields you would expect: name, address, city, state, ZIP code, phone, email, time zone, and operating hours. But two design decisions make it scalable.
Soft deactivation over hard deletion. The table includes an active boolean flag. When a location closes, it is marked inactive rather than deleted. This preserves historical data, maintains referential integrity for classes, coaches, and metrics that reference the location, and prevents accidental reactivation of closed sites. The historical location hierarchy should contain a record for each location referenced in any historical sales records, even if the location is now closed.
Operating hours as a separate table. Rather than storing hours as a single text field, the schema uses a location_operating_hours table with rows for each day of the week, open time, and close time. This structure supports queries like “find all locations open now” without parsing text, and it accommodates complex schedules—split hours, seasonal changes—without schema changes.
Geospatial Indexing: The Engine of Location Intelligence
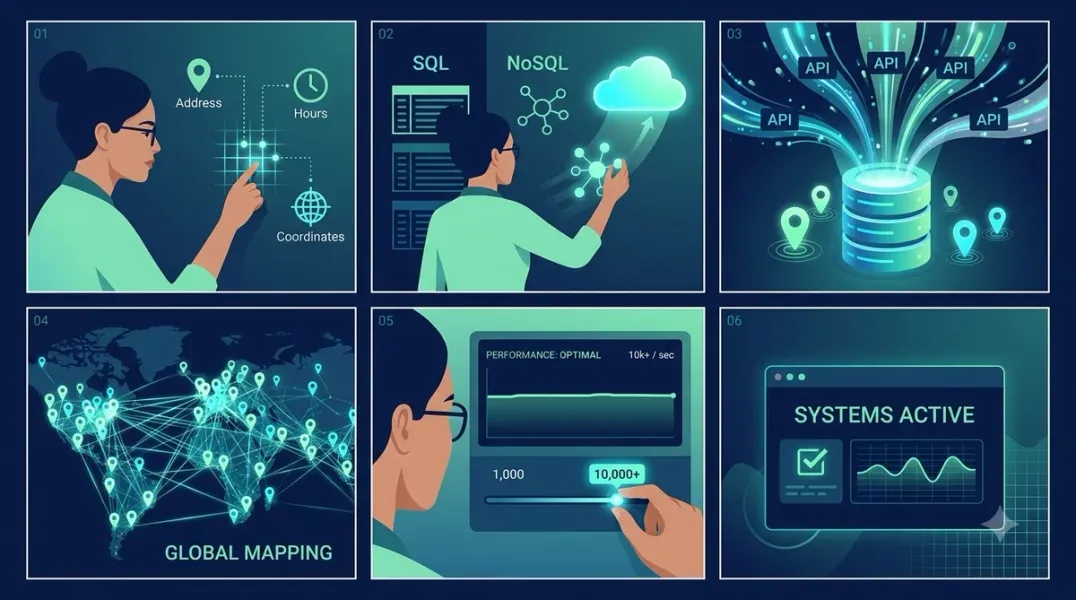
A location database without geospatial indexing is just a contact list. To answer questions like “which stores are within 5 miles of this address” or “which franchise territory contains this customer,” you need latitude and longitude coordinates and an indexing strategy that makes spatial queries fast at scale.
Store coordinates as a derived, indexed property. The Oracle Endeca store locator implementation demonstrates the pattern: latitude and longitude are stored as separate properties, but a derived geocode property combines them into the format latitude,longitude for indexing. When a customer uses a “Search Near Me” feature, the MDEX engine computes the distance to each store using the customer’s location and the indexed geocode values.
Choose the right geospatial engine for your query patterns. Zepto’s journey through geospatial options is instructive. They evaluated PostGIS, Elasticsearch, Google S2, Uber H3, and Redis with custom geohash indexing before selecting Tile38, an in-memory geospatial database built for real-time applications. Tile38 supports points, GeoJSON, geofencing, spatial queries, and live event notifications with replication. For location databases that need real-time “is this address in our delivery zone” queries, the engine choice matters as much as the schema.
The connection pool lesson. Zepto’s scaling challenge was not the database itself but how their application connected to it. Their Redis client used a LIFO (Last-In, First-Out) connection strategy, which meant the most recently used connection was always selected first. Under moderate load, a few connections handled all the work while the rest sat idle. Switching to FIFO (First-In, First-Out) created a round-robin effect that distributed load evenly. If your location queries are slow at scale, the bottleneck may be in how you connect, not what you connect to.
Location Hierarchies and Franchise Territory Management
For franchise networks, a location database must model more than physical sites. It must model the organizational and territorial structures that govern which franchisee is responsible for which area.
Hierarchy keys should not depend on higher levels. The Oracle Promote location hierarchy documentation states a key principle: hierarchy keys should not be dependent on higher levels in the hierarchy. This allows the system to automatically detect and handle hierarchy moves—when a store moves from one region to another—without additional data.
Territory accuracy is a legal and financial issue. Domino’s Pizza Enterprises faced a problem familiar to every franchise network: territory disputes. The franchise contract sets out the territory and number of homes within it, and franchise prices are determined by the number of reachable households overlaid with socio-economic data. Historically, Domino’s used Australian census data, which is only updated every five years. The data quickly became outdated, causing territory disputes and negatively impacting franchisees through lost customers.
Precisely implemented a custom Location Intelligence solution that lets Domino’s govern territories with accurate, up-to-date address data. The solution determines addresses within a territory within minutes, generating a new list every quarter or on demand. This increased delivery reach by providing up-to-date street information from a validated source and improved the customer ordering experience by directing customers to the nearest store based on validated addresses.
Scaling Location Data: The SafeGraph Approach
SafeGraph’s evolution from a few million places to over 80 million locations across 200+ countries offers lessons in how to scale a location dataset while maintaining quality.
Expand coverage in deliberate phases. SafeGraph started with places where people spend money—retailers and restaurants. They then expanded to places where people spend time but not necessarily money: parks, schools, offices, warehouses. They then incorporated small-footprint POIs like EV charging stations and ATMs. Finally, they began appending new attributes such as store ID and category tags.
Verify that places are real. As datasets grow, the risk of false positives increases. SafeGraph constantly verifies that places in their dataset are truly open and operating. They filter out online-only stores and event names mistakenly treated as venues. The long-term precision of the dataset and customer trust go hand in hand.
Use high-veracity sources as baselines. SafeGraph captures baseline information from sources known for accuracy, such as the Starbucks Store Locator, which must remain current to serve customers effectively. For your location database, establish similar source hierarchies: which systems are authoritative for which fields, and how discrepancies are resolved.
Automation: Keeping the Database in Sync
A location database that scales is a database that stays current without manual intervention. Google My Business automation connects the database to external platforms, syncing location details when fields like address, phone, or opening hours change.
Event-driven architecture. When a location’s operating hours change in your database, that change should trigger validation of affected systems (like class schedules in a fitness franchise) and publish a LocationUpdatedEvent consumed by scheduling, coaching, and notification systems. The database is not just a passive store—it is an active source of truth that propagates changes.
Automation risks to manage. Before automating profile updates, consider risks like incorrect business details spreading quickly across search, maps, and reviews. Automation tools can mishandle duplicate listings, suspensions, or policy changes if not closely monitored. Data security, access control, and unreliable integrations can disrupt visibility and confuse customers.
Central source of truth. The most reliable automation syncs location data from a single source so changes are applied uniformly. Regular review of automation rules ensures ongoing updates stay accurate and aligned with real-world operations.
A Scalable Data Model: Putting It Together
Combining these lessons, a location database schema that scales includes:
Core location table: Unique identifier (UUID), name, address fields, phone, email, time zone, coordinates (latitude/longitude), soft-delete flag, created timestamp.
Operating hours table: Location ID foreign key, day of week, open time, close time, with support for multiple periods per day.
Hierarchy table: Location key, hierarchy level, parent node, with keys independent of higher levels to support moves.
Geospatial index: Derived geocode property (latitude,longitude) indexed for spatial queries, or integration with a dedicated geospatial engine for real-time queries.
Event stream: Location created, updated, deactivated events that trigger downstream synchronization and validation.
Territory data: For franchise networks, boundary definitions and address lists generated from validated sources, updated on a defined schedule.
Conclusion
A location database that scales is not a bigger spreadsheet. It is an engineered system with deliberate choices about schema design, geospatial indexing, hierarchy management, and automation. The challenges Zepto faced at scale—connection pool imbalances, uneven load distribution—are predictable outcomes of architecture that was not designed for growth. Domino’s territory disputes and SafeGraph’s false-positive filtering are the same lesson from different angles: scale introduces complexity that must be managed, not avoided.
Build the schema with soft deletes and separate hours tables. Index coordinates for spatial queries. Model hierarchies with independent keys. Connect the database to external platforms through event-driven automation. And verify that your places are real places, not records that should have been deleted years ago.
Call to Action
Ready to architect a location database that will not break at the next expansion? Download our Scalable Location Database Blueprint to review schema designs, geospatial indexing patterns, and automation integration points. Or schedule a consultation to assess your current location data architecture.
FAQs
Q: What is the most important field in a location database for scaling? A: A unique, permanent identifier for each location. This ID anchors records across systems even when other details change. Soft-delete flags preserve historical data without breaking referential integrity.
Q: How do I handle geospatial queries at scale? A: Store latitude and longitude as indexed coordinates. For real-time spatial queries, consider a dedicated geospatial engine like Tile38. Also audit your connection pool strategy—LIFO patterns can create bottlenecks even when the database itself performs well.
Q: What should happen to a location record when a store closes? A: Mark it as inactive (soft delete) rather than deleting it. The historical hierarchy should retain a record for each location referenced in historical sales data, even if the location is now closed.
Q: How do franchise networks manage territory data accurately? A: Use validated address data rather than census data or manual street lists. Generate territory address lists on a defined schedule (quarterly or on demand) using a Location Intelligence solution that provides up-to-date information on new builds, demolitions, and building use changes.
Q: How can I keep my location database in sync with Google and other platforms? A: Implement event-driven automation. When location details change in your database, trigger updates to external platforms through APIs. Monitor for risks like duplicate listings and policy changes, and maintain a central source of truth for all location data.
Internal & External Links
Internal Links
- How to Build a Master Location Database for Local Marketing Teams
- How to Create a Business Profile Data Dictionary for Multi-Location Brands
- How to Map Local Marketing Workflows Before Implementing Automation
External Sources
- Zepto: Boosting Geospatial Performance with Tile38 https://blog.zeptonow.com/boosting-geospatial-performance-at-zepto-learnings-from-scaling-tile38-c31fd1b5ebc2
- Precisely: Domino’s Pizza Franchise Planning Case Study https://www.precisely.com/resource-center/customerstories/dominos-pizza-streamlines-franchise-planning-using-location-intelligence
- SafeGraph: How Our Definition of a Place Has Evolved https://www.safegraph.com/blog/how-our-definition-of-a-place-has-evolved/
Grow Your Google Maps Ranking on Autopilot
Stop spending hours every week manually replying to customer reviews and writing Google posts. Busirank automates your Google Business Profile to boost your local SEO rankings and turn searchers into paying clients.
 Busirank Team